












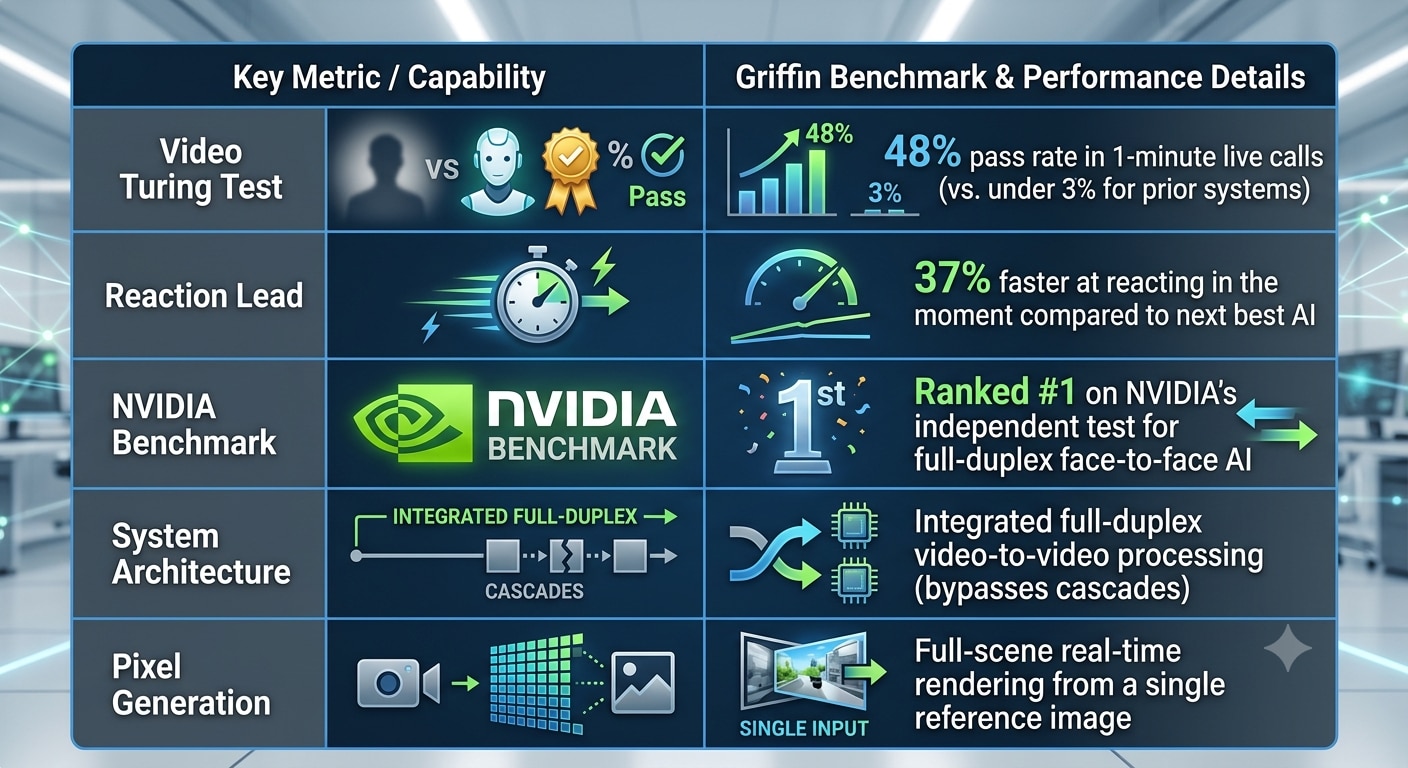



Machine interaction took a dramatic step toward human-like fluidity today as AI firm Tavus announced Griffin, an end-to-end Human Interaction Model (HIM) engineered to perceive and conduct real-time, face-to-face video conversations.
Unlike traditional conversational AI setups that rely on a stitched-together cascade of text transcription, large language model generation, and separate voice or video synthesis, Griffin operates as a single, full-duplex video-to-video pipeline.

 ₹1.50 lakh gold tests Indian consumers: Lightweight jewellery gains traction
 Small-cap funds under pressure in September: Only 4 schemes deliver positive returns
 'No amount of money can ever...': Mankind Pharma honours flydubai pilot Smit Machchhar with ₹1 crore
 Saudi plans military push in Yemen to wrest Bab el-Mandeb from Houthi control
 Flydubai mid-air attack: Co-pilot who attacked Indian pilot had been flagged as security risk, says report
 5-10 Year Wealth Creation: How Should Investors Build Their Long-Term Portfolio?
 How Much Should You Invest In Bonds At Different Stages Of Life? 20/60 Investing Rule Explained
 Bond Investing For Beginners: How To Choose, Check Ratings, Returns & Manage Risk
 Flexi-Cap Funds: How Much Does the Fund Manager’s Strategy Really Matter?
 Diwali 2026 Gold Price Outlook | Expert Price Targets Revealed | Massive Gold Price Prediction

 Stock market sell-off: Nifty, Sensex log 8th straight weekly loss; key levels & top triggers now
 IPO boom: 69 Indian companies raise Rs 90,500 crore in Q3 despite stock market sell-off; what's next
 TCS, Infosys, HCL Tech, TechM, Wipro, LTM, Coforge, HEXT: Fresh target, Q2 previews for IT stocks
 Carlsberg India IPO: SEBI approves confidential filing; beer maker moves closer to listing
 Suzlon, KPIT Tech, RIL, IRFC, HDFC Bank, Infy: 56% Nifty500 stocks in bear grip amid market sell-off'No amount of money can ever...': Mankind Pharma honours flydubai pilot Smit Machchhar with ₹1 crore
 India's next strategic asset: Sovereign intelligenceSaudi plans military push in Yemen to wrest Bab el-Mandeb from Houthi control
 Gold, silver prices on October 3: Check latest rates in Delhi, Mumbai, Kolkata, other cities5-10 Year Wealth Creation: How Should Investors Build Their Long-Term Portfolio?


